To remove duplicates in Excel, select your complete dataset, choose Data > Remove Duplicates, and tick the columns that define a duplicate. Before selecting OK, decide which record should survive and make a backup.
That last part matters more than the button. Two rows with the same email address may be different orders, different contacts, or an old and a new version of one record. Deleting duplicates without a clear rule can remove information you meant to keep.
First Decide What “Duplicate” Means
A duplicate is a match against your chosen comparison columns. It is not automatically a mistake.
Use this small example. The Row label is for tracking where each record came from, not part of its business identity.
| Row | Product | Updated | Status | |
| R1 | alex@example.com | Starter | 2026-10-02 | Pending |
| R2 | blair@example.com | Pro | 2026-10-04 | Active |
| R3 | alex@example.com | Starter | 2026-10-06 | Active |
| R4 | alex@example.com | Pro | 2026-10-07 | Active |
| R5 | blair@example.com | Pro | 2026-10-04 | Active |
There are at least three reasonable rules:
| Columns compared | Meaning | Rows retained in the current order |
| Email only | One record per email | R1, R2 |
| Email and Product | One record per email-product combination | R1, R2, R4 |
| Email, Product, Updated, Status | Remove only matching business records | R1, R2, R3, R4 |
Including the unique Row label in the comparison would make every row different. Exclude tracking IDs when the purpose is to find otherwise identical records.
Notice that Email-only matching deletes R4, even though it refers to a different product. That may be wrong for an order history, but right for a deliberately simplified contact list. Choose the rule before you choose the checkboxes.
Back Up the Data and Preserve Row Order
Save a copy of the workbook or duplicate the source sheet. Add an Original row column with fixed sequential values when you need to restore the original order later. If you use a formula to create those numbers, paste them as values before sorting.
Also decide whether you want the first record, newest record, lowest-priced record, or most complete record in each group. “Keep whichever happens to appear first” is a choice, even when you do not make it consciously.
Microsoft recommends copying the original data before removing duplicates, because the command deletes duplicate values from the selected data. A backup is safer than relying on Undo after several other edits.
Remove Duplicates from a Single Column
For a standalone list of email addresses, select the list and its header. Then open Data > Remove Duplicates, confirm that My data has headers matches your selection, and leave the email column checked.
Choose OK and review the result. The command keeps the first occurrence in the current order and removes later matches.
If that email column belongs to a wider table, select the whole related table, not only the email cells. Otherwise, you risk separating emails from their names, prices, or order details. If Excel asks whether to expand the selection, include the related columns that must stay together.
The desktop Windows ribbon shortcut is often Alt, A, M, pressed in sequence. The menu route is the clearer choice when keyboard shortcuts differ by version or language.
Remove Duplicate Rows Using Multiple Columns
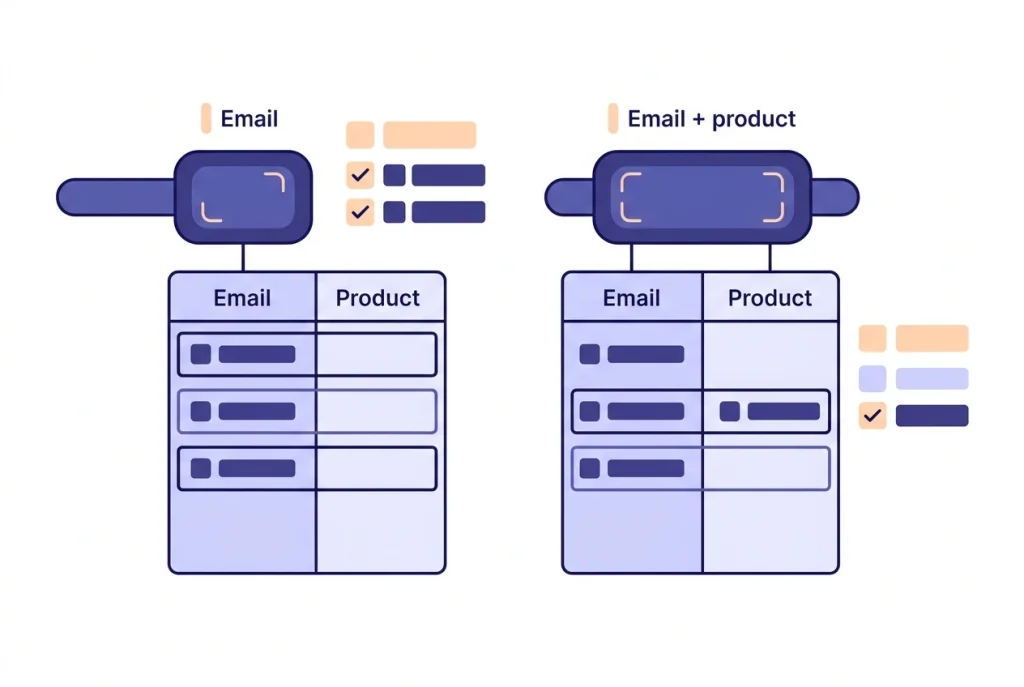
To keep one row for each email-product combination in our example:
- Select the full table, including every column that belongs to each record.
- Open Data > Remove Duplicates.
- Confirm the header setting.
- Clear the comparison checkboxes, then tick Email and Product only.
- Select OK and compare the surviving row labels with the expected result.
The result in the original order is R1, R2, and R4.
Unchecked columns are not protected from removal. They simply do not help decide whether a row matches. When Excel removes a duplicate record within your selected range, its other selected fields go with it. The Status field does not survive separately because you left its checkbox unticked.
Microsoft’s detailed duplicate guidance distinguishes filtering from deletion and explains that values outside the selected range are not changed. This is another reason to include all related columns in your selection.
ADD YOUR IMAGE 2 HERE
Keep the Newest Record Instead of the First Old One
Suppose you need the latest status for each email-product combination. Sort the entire table by Updated, newest to oldest, before removing duplicates using Email and Product.
The rows now begin with R4, then R3, then the two Blair records, and finally R1. Removing duplicates keeps R4 and R3, plus one Blair record.
Add a second sort level using Original row, smallest to largest, to make ties predictable. With that rule, R2 wins the tie against R5. The final retained set is R2, R3, and R4. Their displayed order depends on whether you leave the date sort in place or sort the retained rows back by Original row.
For this to work, the Updated values must be real Excel dates, not a mixture of text and dates. Check a few cells before sorting. A newest-first label is not enough if Excel is sorting some values as text.
The same principle can keep the cheapest record: sort the full table by Price, smallest to largest, then deduplicate using the intended identity columns. Define what to do with missing prices first. A blank price is not automatically the best offer.
Do not Delete Rows that Should be Combined
Consider two orders from the same customer: one for $25 and another for $40. Removing one of those rows loses a sale. If your goal is “total spending per customer,” you need aggregation, such as a PivotTable or a SUMIFS calculation, rather than duplicate removal.
Likewise, keeping the newest row may discard an older phone number that is missing from the newest record. A “most complete contact” rule may require merging fields or manual review.
Ask one question before deleting: Am I removing repeated copies, choosing a representative record, or combining information? Those are three different tasks.
Keep the Original Intact with UNIQUE
For a separate list of distinct email addresses in supported Excel versions, enter:
=UNIQUE(A2:A100)Use a bounded source range and place the formula outside the source data, with enough empty cells below it for the results. To return distinct combinations across several columns, use a multi-column range instead:
=UNIQUE(A2:D100)This creates a separate result rather than deleting the original rows. It does not automatically choose the newest row by one column while carrying other fields along.
There is also an important distinction between distinct values and values that occur only once. The default UNIQUE result includes one copy of every distinct value. Setting its third argument to TRUE returns only entries that appear exactly once:
=UNIQUE(A2:A100,,TRUE)For Alex, Alex, Blair, the default returns Alex and Blair. The exactly-once version returns only Blair. Microsoft’s UNIQUE documentation explains this argument and lists supported versions, including Microsoft 365, Excel 2024, and Excel 2021.
Why Apparent Duplicates May Remain
Inspect the comparison fields rather than repeatedly pressing Remove Duplicates. Extra spaces, hidden characters, inconsistent dates, or different underlying identifiers can make visually similar records behave differently.
For text copied from websites, a helper such as this can normalize ordinary spacing and nonbreaking spaces:
=TRIM(SUBSTITUTE(A2,UNICHAR(160)," "))Keep the original field beside the cleaned field. Only use the cleaned field as your key after confirming that the cleanup preserves meaning. Do not strip punctuation from product codes or turn identifiers such as 00125 into numbers without a reason.
For case-sensitive IDs, mixed data types, or complex matching rules, test the behavior on a small copy before trusting the basic command. Similar-looking text is not a sufficient data policy.
Verify the Surviving Records
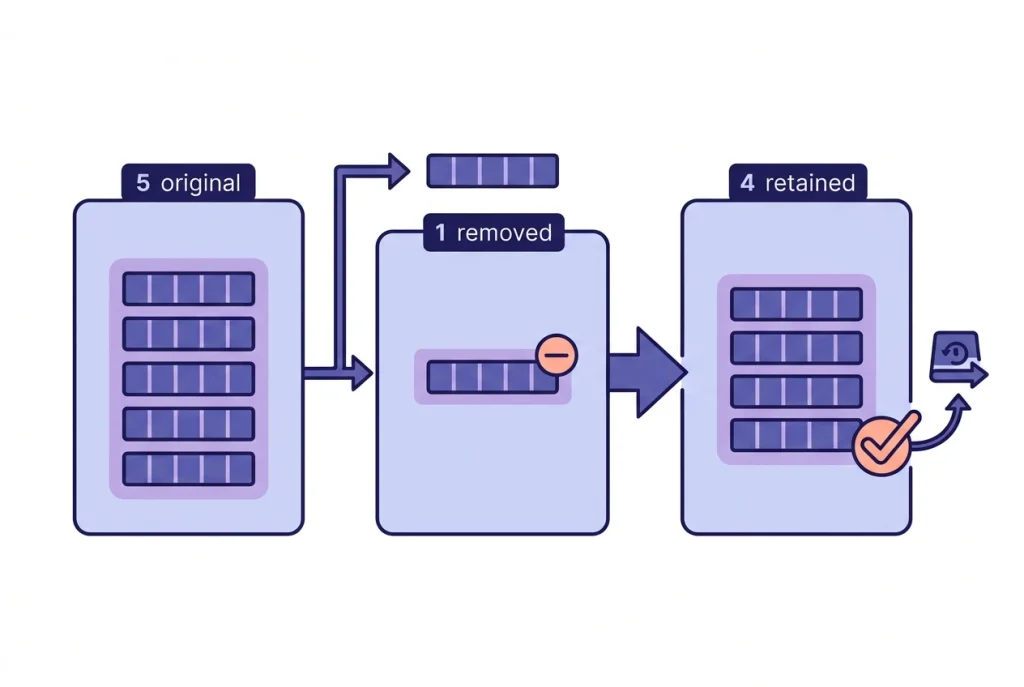
For our five-row sample, the counts should be:
| Rule | Original rows | Removed rows | Remaining rows |
| Email only | 5 | 3 | 2 |
| Email and Product | 5 | 2 | 3 |
| All four business fields | 5 | 1 | 4 |
The arithmetic should reconcile: original rows equal removed rows plus remaining rows. Count records using a reliably populated ID column, not an optional field that may be blank.
Then inspect at least one duplicate group manually. Did the intended status, date, and price survive together? A correct row count does not prove that you kept the right rows.
For simple pasted text with one entry per line, the NavigationHubs Duplicate Line Remover is a separate option. It is not a substitute for Excel’s column-based matching or a rule that keeps the newest record.
The takeaway: define the matching columns, define the survivor, preserve the complete row, and verify the output. Removing duplicate rows is easy; removing only the rows you truly do not need takes a clear rule.